🔍 Read the full analysis: Up To 14% Better AMD Chip Designs? What OpenAI’s Models Actually Measured on ThorstenMeyerAI.com

Prime made for students and young adults
- Fast, free delivery for dorm and study essentials
- Prime Video and Amazon Music included
- Member-only deals
TL;DR
OpenAI says its models rewrote parts of AMD chip designs and produced up to 14% gains in power, performance and area against heavily optimized baselines. The figure is a best case, and public accounts do not identify the blocks measured or provide independent verification. OpenAI also reports smaller-area results for its own chip and single-digit gains in selected AMD CPU blocks.
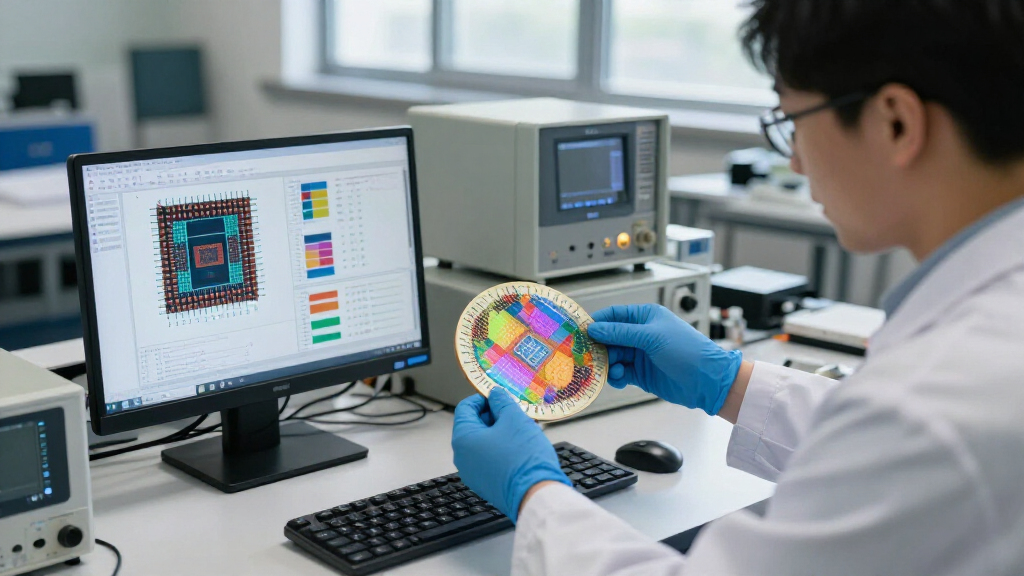
OpenAI said on November 18 that its models rewrote parts of an AMD flagship GPU design, producing up to 14% improvements in power, performance and area, or PPA, compared with heavily optimized baselines. The company said some model-generated changes were included in a design AMD sent for manufacturing, but the public information does not identify the affected blocks or show an independent audit of the results.
The headline figure is an “up to” result, not a reported average across the GPU. OpenAI’s account, as summarized by ANI and other outlets, describes a comparison against AMD designs that engineers had already optimized. It does not specify which circuit blocks delivered the best result, how much of the chip they represent, or whether the stated PPA was measured after synthesis or after later physical-design steps such as placement and wiring.
OpenAI also reported that AMD verified single-digit percentage gains in performance, power and area for key blocks of its next flagship CPU. That is a separate result from the GPU’s up-to-14% figure. AMD has not published its own measurements or a detailed technical account in the material available for this report. CEO Lisa Su praised the work on X, according to Stocktwits.
For its own custom inference chip, Jalapeño, OpenAI said model-proposed changes reduced standard-cell area by about 13% in one unit and 10% in another. The company said those changes were validated when the first chips returned from manufacturing. Reports use different names for the first unit, describing it as either a warp engine or a vector unit. OpenAI also said it tested five models on two open-source RISC-V processor cores, PicoRV32 and Ibex, across 9,881 scored runs; GPT-6.2 Astra achieved the highest score in that evaluation.
AI Moves Into Chip Design
The reported work points to a practical way AI could assist a slow, costly part of developing computing hardware: proposing alternative circuit descriptions for engineers to test. If the improvements persist in manufactured chips, better PPA could let a company deliver more performance within power and area limits, or reduce the resources needed for a given task. Those trade-offs matter as AI workloads increase demand for accelerators and the chips that run them.
The evidence supports a narrower conclusion than the headline number alone may suggest. OpenAI says its models produced candidate changes, while conventional Synopsys design tools checked behavioral equivalence and measured trade-offs. That division of labor is significant: the models did not, according to the reports, establish correctness on their own. Chip designs must preserve intended behavior, and manufacturing an error can be expensive. The reported results show a potential engineering aid, not proof that models can independently design a complete production chip.
There is also a commercial interest to keep in view. OpenAI holds a warrant for up to 160 million AMD shares, granted in October 2025, that vests as AMD chips are deployed. That relationship does not disprove the technical claims, but it makes detailed disclosures and outside verification particularly relevant when evaluating results announced by OpenAI.
Popular right now

Vitamix VX1 Professional-Grade Blender, 64 oz, Black

Bose QuietComfort True Wireless Earbuds with Active Noise Cancellation, Bluetooth 5.3, USB-C Charging, IPX4, Black

Dyson V9 Motorbar Cordless Vacuum
As an affiliate, we earn on qualifying purchases.
What the Models Actually Changed
The reported work took place at the register-transfer level, or RTL, where engineers describe a chip’s functions in code, including how they operate from clock cycle to clock cycle. Synthesis software converts RTL into logic gates; later design stages arrange and connect those gates for manufacture. The OpenAI announcement concerns changes to this coded representation, rather than a claim that a model independently produced a finished chip.
According to OpenAI’s account as described by Inside AI, a model can propose different logic, divide calculations differently across pipeline stages, share hardware, or reduce intermediate storage while preserving a block’s function. For Jalapeño, the outlet described a multiplier redesign that used about 15% less cell area in synthesis while reducing latency from two clock cycles to one, and an adder redesign that cut cell area by about 15% at the same two-cycle latency. These examples concern specific units and synthesis measurements; they should not be treated as the reported whole-chip AMD result.
OpenAI’s November 18 post, titled “Advancing chip design with OpenAI models,” is the primary source for the claims. The article’s source material says an automated request to the post was refused, so details are drawn from reports by ANI, The Decoder and Inside AI, which agree on key figures. OpenAI president Greg Brockman described the AMD result on X as “roughly an additional year of progress” achieved in less than five months using the company’s models. That is a characterization of the pace of work, not a separately published measurement of engineering time saved.
“Su praised the results on X.”
— AMD CEO Lisa Su, as quoted by Stocktwits
Missing Blocks and Independent Checks
The public reporting does not give the names or size of the AMD GPU blocks behind the 14% best-case figure, the average gain across changes, or the exact measurement stage. It also does not provide full test conditions, detailed results for each PPA metric, or an independent audit. Without those details, readers cannot determine how representative the highest result is or how it would translate into whole-chip performance.
OpenAI says some changes went into a design AMD sent for manufacturing and others into production design files for future versions. The available accounts do not identify the specific changes, say when the submitted design will be available as a product, or report its measured performance after manufacture. AMD’s single-digit CPU result is also described through OpenAI’s account; AMD has not supplied figures of its own in the source material.
The Jalapeño area results have a different evidentiary status from the AMD claims: OpenAI says it validated them when first chips returned from fabrication, while the AMD GPU’s manufacturing and post-silicon outcomes are not detailed. The disagreement in reports over the name of one Jalapeño unit also remains unresolved. The commercial relationship between OpenAI and AMD is disclosed, but its effect, if any, on the reported design work or measurements is not established.
Verification After Manufacturing
The next useful evidence would be a technical breakdown from OpenAI and AMD identifying the affected blocks, baseline designs, measurement methods and results for each PPA measure. Post-manufacturing data would help show whether the improvements observed in design tools carry through to fabricated hardware. AMD’s own account could clarify how its engineers verified the CPU gains and which changes were accepted into production designs.
For now, the clearest confirmed development is that OpenAI has publicly described model-generated RTL changes and reported results across AMD designs and its own Jalapeño chip. Whether the best-case 14% figure generalizes across a meaningful portion of the GPU, and what it means for a shipping product, remain open questions.
Key Questions
What does “up to 14% better” mean here?
OpenAI reported a best-case improvement in power, performance and area against heavily optimized baselines. It did not publish an average across the GPU or identify the blocks behind the maximum.
Did OpenAI’s models design an entire AMD chip?
No such claim is established in the source material. The models reportedly rewrote portions of RTL code, which describes circuit behavior. Conventional design tools checked the proposed changes, and engineers remain part of the design and verification process.
Has AMD independently confirmed the 14% figure?
The material attributes the GPU result to OpenAI. OpenAI separately said AMD verified single-digit gains in key blocks of a next flagship CPU. AMD has not published its own detailed figures in the cited source material.
Were any changes manufactured?
OpenAI said some model-generated changes were included in an AMD design sent for manufacturing. The public accounts do not identify those changes or provide post-manufacturing measurements for that design.
Why is the OpenAI-AMD relationship relevant?
OpenAI holds a warrant for up to 160 million AMD shares that vests as AMD chips are deployed, according to the source material. This disclosed commercial tie does not settle whether the technical results are accurate, but it is relevant when weighing claims that have not received an independent public audit.
Source: ThorstenMeyerAI.com