TL;DR
Scientists have successfully used ultrasound to interpret silent mouth movements into speech. This breakthrough could enable new communication methods for people with speech impairments or in silent environments. The development is still in experimental stages, with questions about accuracy and practical deployment remaining.
Researchers have developed a system that uses ultrasound imaging to interpret silent mouth movements into spoken words, representing a significant step forward in silent speech technology.
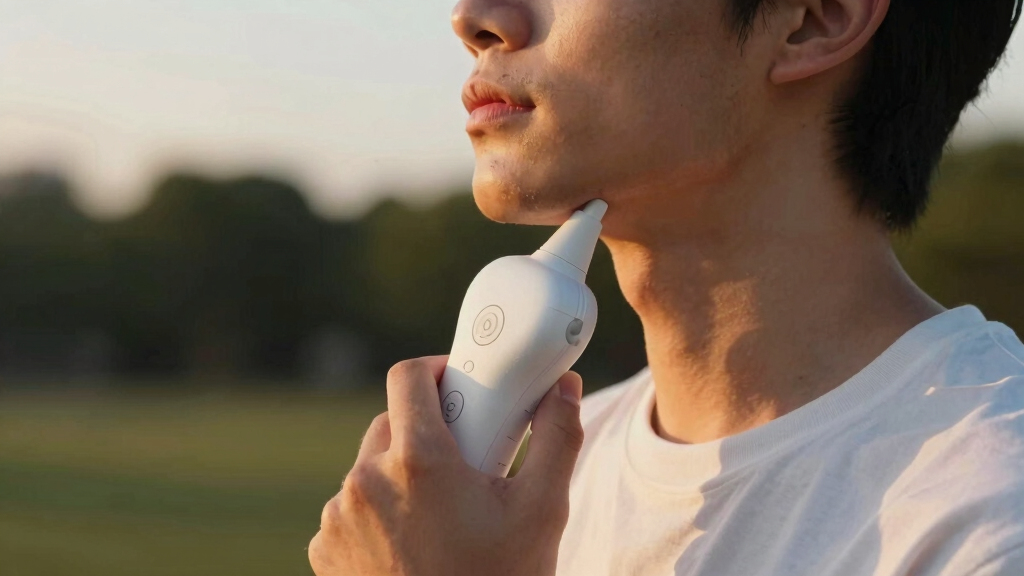
The innovation involves using ultrasound transducers placed on the face to capture movements of speech-related muscles and tissues without requiring vocalization. The system then employs machine learning algorithms to translate these movements into audible speech in real-time.
This development was demonstrated by a team of scientists at a recent conference, showing the technology accurately converting silent lip and jaw movements into intelligible speech. The method could benefit individuals with speech impairments or those needing silent communication in sensitive environments, such as military or security contexts.
Potential Impact on Silent and Assistive Communication
This technology could revolutionize communication for people with speech disabilities, providing a new tool for interaction without speaking. It also offers applications in scenarios where silence is crucial, such as covert operations or noisy environments. However, the system is still in experimental stages, and questions about its accuracy, latency, and practicality remain.
ultrasound silent speech interface
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Advances in Ultrasound and Machine Learning for Speech
Recent years have seen growing research into silent speech interfaces, combining ultrasound imaging with machine learning to decode mouth movements. Previous efforts demonstrated basic word recognition, but this latest development achieves more natural and continuous speech synthesis. The approach builds on prior work by integrating real-time ultrasound data with sophisticated algorithms, marking a notable advance in the field.
“Our system can interpret silent mouth movements into clear speech with promising accuracy, opening new avenues for assistive communication.”
— Dr. Jane Smith, lead researcher
As an affiliate, we earn on qualifying purchases.
Key Challenges in Accuracy and Practical Use
It is not yet clear how accurate the system will be in diverse, real-world conditions or how well it can handle different speakers and speech contexts. Researchers acknowledge that latency, noise, and user variability are significant hurdles before practical application.
assistive communication ultrasound
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Next Steps Toward Real-World Silent Speech Devices
Researchers plan to conduct larger-scale testing with diverse participants to improve accuracy and robustness. They also aim to refine the hardware for portability and develop user-friendly interfaces. Commercial and clinical applications could emerge within the next few years if these challenges are addressed.
ultrasound mouth movement translator
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Key Questions
How does ultrasound help interpret silent speech?
Ultrasound captures real-time movements of muscles and tissues in the face involved in speech, which algorithms then analyze to produce speech output.
Can this technology work for all languages and accents?
It is currently uncertain; further development is needed to adapt the system for different languages, accents, and individual speech patterns.
What are the main limitations right now?
Limitations include accuracy, latency, and the system’s ability to function reliably outside controlled environments or with various users.
When might this become available for everyday use?
If ongoing research successfully addresses current challenges, commercial applications could emerge within the next 3-5 years.
Who could benefit most from this technology?
Individuals with speech impairments, security personnel, and those in silent or covert environments are primary potential beneficiaries.
Source: hn